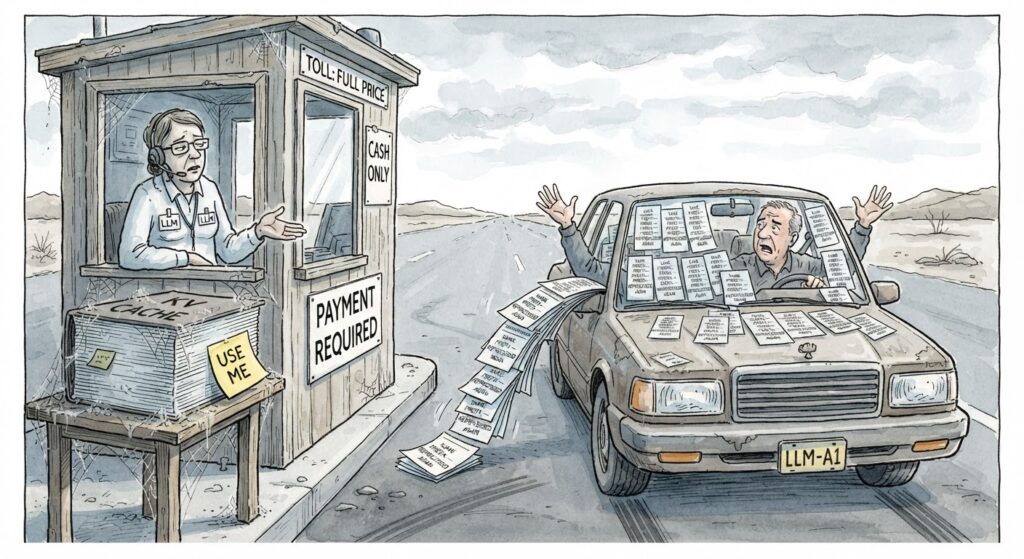
You are paying full price for work the model already did
Every time your application sends a long system prompt, a document context, or a RAG payload to an LLM, the model reprocesses every token from scratch — unless caching is active. That reprocessing is not cheap. For large models, preprocessing input tokens through the transformer layers is often more expensive than generating the actual answer output. DEV Community puts it plainly: “Prompt caching exists to avoid that waste.”
Prompt caching stores the transformer’s internal Key-Value (KV) tensors — not the text, not the final response — so that identical prompt prefixes skip full reprocessing on subsequent requests. A commenter on the SAP Community captured the distinction precisely: “Prompt caching does not cache the answer. It caches the question.” That difference has direct operational consequences.
What the numbers actually show
The headline figures are significant. Prompt caching cuts input token costs by 50–90% and reduces latency by up to 80%, according to a February 2026 analysis by Michael Hannecke on Medium. On the cost side, Anthropic’s Claude prices cache reads at 90% less than fresh processing, with repeated prompt prefixes cached for up to five minutes, per SurePrompts (April 2026).
Those figures carry assumptions worth unpacking. The 90% reduction applies specifically to cache hit reads. A cache write — the first time a prefix is processed and committed to the backing store — carries its own cost. As Majromax explained on Hacker News: “That’s why a ‘cache write’ can carry a cost; it is the cost of both processing the input and committing the backing store for the cache duration.” The savings are real, but they accrue only after that first write. High-frequency, repeated prefixes unlock the full benefit. Low-frequency or highly variable prefixes may not recover the write overhead at all.
The memory cost is also non-trivial. The KV cache requires one entry per input token per model layer, with each entry being an O(1000)-dimensional vector — making memory cost linear in context length. Majromax describes it as “very heavyweight.” Providers absorb this infrastructure cost and pass a portion of the savings to you. A lower cache hit rate lowers your return; that is the honest version of the deal on the table.
Provider landscape: automatic vs. explicit caching
Every major LLM provider now supports prompt caching, though the implementation model differs. OpenAI and DeepSeek handle it automatically — zero configuration required. Anthropic and Google Gemini offer both implicit and explicit modes; explicit caching lets you designate specific prefix boundaries. Hannecke’s February 2026 analysis puts the implementation cost at “zero (OpenAI, DeepSeek) to a few lines of configuration (Anthropic, Gemini).”
Explicit caching gives you more control over what gets cached and when, but it requires deliberate prompt structuring. The guidance from the same source: place static content first, dynamic content last. If more than 50% of your input tokens repeat across requests, caching should be enabled. Below that threshold, write overhead may outweigh read savings.
Where gains differ by workload type
Not all workloads benefit equally.
- AI agents with long system prompts — The same instructions repeat on every turn. Caching the system prompt prefix reduces both cost and latency once the first write is committed.
- RAG pipelines with static document chunks — If the same document is retrieved across multiple user queries, its KV tensors need computing only once per cache window. High-volume RAG deployments are the strongest case for explicit caching.
- Conversational applications with short, variable prompts — These see the smallest gains. Each user message is unique, and the static prefix may represent only a small fraction of total input tokens, limiting the cacheable surface area.
NeuralTrust (April 2026) draws a useful distinction between prompt caching and semantic caching. Semantic caching stores final answers to repeated questions. Prompt caching stores the model’s internal understanding of a prompt prefix. They are complementary, not competing. Operators running high-volume FAQ or support workloads may benefit from layering both.
The determinism objection, examined fairly
Some engineering teams avoid caching on the assumption that it changes model behaviour. The concern is understandable, but the mechanism is misunderstood. Prompt caching skips recomputation of the KV tensors for a cached prefix; it does not alter the model’s weights or sampling logic. The model continues from the cached state as it would from a freshly computed one.
The actual source of non-determinism is elsewhere. Setting Temperature=0 does not guarantee identical outputs even with caching enabled, due to Mixture-of-Experts (MoE) routing and GPU-level non-determinism, according to the SAP Community (December 2025). That variance exists with or without the cache. Avoiding caching to preserve reproducibility does not eliminate the problem — it only adds cost and latency.
Three operator decisions the evidence supports
Audit your prompt structure before enabling caching. If dynamic content appears before static content — user messages before system instructions — you are likely getting zero cache hits even on providers with automatic caching. Restructuring to static-first is the highest-leverage single change available.
Measure your prefix repetition rate before projecting savings. The 50–90% cost reduction applies to the cacheable portion of your input tokens. A workload where 30% of tokens are static will see proportionally smaller gains than one where 80% are static. Model the actual number for your pipeline before building a business case.
Keep prompt caching and semantic caching distinct in your evaluation. Prompt caching reduces the compute cost of processing a shared prefix. Semantic caching avoids calling the model at all for repeated questions. Deploying both — where the workload supports it — typically yields the largest combined reduction in cost and latency.
The implementation barrier is low. The savings are real but conditional. The main variable is whether your prompt architecture is structured to produce cache hits in the first place.
Eagentix helps growth-focused enterprises redesign and automate manual business processes. We combine executive strategy, implementation support, and managed services to build dependable operations across Southeast Asia.
Sources
- – Prompt Caching in LLMs: The Hidden Optimization Saving Millions of GPU Hours – DEV Community
- – 50 Prompt Engineering Interview Questions and Answers (2026) | SurePrompts
- – Beyond Stateless: Prompt Caching as the Working Memory for AI Agents | NeuralTrust
- – An update on recent Claude Code quality reports | Hacker News
- – The Hidden Behavior of LLMs – Prompt Caching and D… – SAP Community
- – Prompt Caching: What It Is, What It Is Not | Medium
- – What is Prompt Caching? Optimize LLM Latency with AI Transformers
- – Prompt Caching breakdown: Cut token spend in 2026
- – What Is Prompt Caching? LLM Speed & Cost Guide
- – Prompt Caching on SambaCloud: Faster, Cheaper Inference
- – How does Prompt Caching work?
- – Prompt Caching Explained | DigitalOcean
- – How prompt caching works – Paged Attention and Automatic Prefix Caching plus practical tips
- – Prompt caching – Fireworks AI Docs
- – Prompt Caching with OpenAI, Anthropic, and Google Models
- – Medium
- – Prompt Caching – GroqDocs
- – Caching for LLMs: Prompt, Semantic, and Invalidation – Interactive
- – Prompt Caching Visually Explained – Cloud Girl
- – Prompt Caching Explained: Stop Overpaying for AI Agents
- – Prompt Caching in 2026: Cut LLM Costs, Keep Quality