The bill arrives before the strategy does
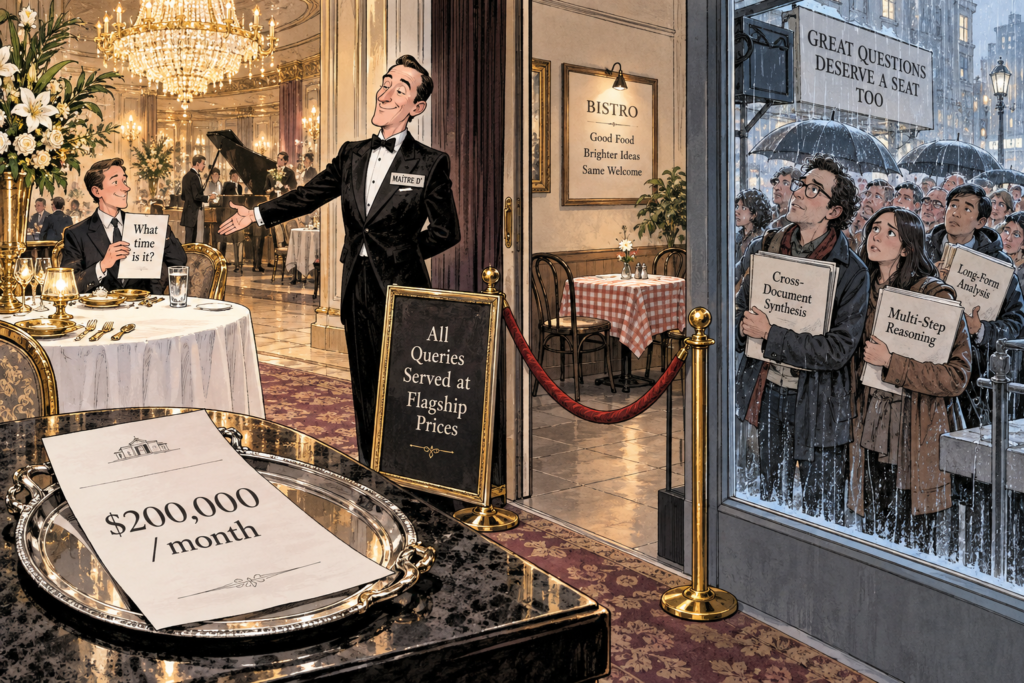
At one enterprise partner studied in the RouteNLP research, inference costs exceeded $200K per month — despite over 70% of queries being routine tasks well within the capability of smaller models. RouteNLP (Guo et al., 2026) That figure describes the default: send everything to the flagship, pay flagship prices, and call it a production system.
The default persists because it feels safe. One model, one API key, one bill you can at least explain. But the cost structure compounds quickly once query volume scales. The question worth asking in 2026 is not whether to route, but how to implement it without introducing new failure modes.
What routing actually means in production
Routing, in the technical sense, is query-time model selection: a lightweight classifier inspects an incoming request and assigns it to the most cost-appropriate model in your pool. It is distinct from cascading, where you attempt the cheap model first and escalate on failure, and from ensembling, where multiple models vote. A Systematic Survey of Large Language Model Routing (EMNLP 2026) distinguishes these designs explicitly — and the distinction matters operationally, because each carries different latency, quality-risk, and calibration requirements.
The underlying premise is straightforward. Queries vary substantially in complexity, from single-turn intent classification to cross-document synthesis requiring multi-step inference. Dynamic Model Routing and Cascading: A Survey (TMLR, 08/2026) Static deployment sends every query to the same model regardless of that complexity, wasting compute on the easy majority while paying the same per-token rate on the hard minority.
RouteNLP tested a closed-loop framework that routes across a tiered model portfolio to minimise cost while satisfying per-task quality constraints. Its reported results: 62% cost reduction on benchmark tasks and 58% in a live pilot, while retaining 96–100% quality on structured tasks and 96–98% on generation tasks. Human evaluation confirmed that 74.5% of routed generation outputs matched or exceeded frontier-model quality. RouteNLP (2026) These are pilot figures from a single enterprise partner, not guaranteed production outcomes. They indicate the order of magnitude available when routing enforces quality constraints rather than optimising for cost alone.
Where the evidence is strong — and where it is not
The 2026 benchmark literature is clearest on narrow, schema-bound tasks. Intent classification, structured field extraction, tool selection, payload formatting, and single-turn tool use are tasks where small models perform reliably. IoT Digital Twin PLM benchmark (June 2026) The condition is that a deterministic validator can catch the occasional miss before it reaches the user. Without that backstop, routing to a small model on these tasks is a bet, not a control.
Agentic workflows introduce a specific complication. AgentRouter, a 12M-parameter classifier presented at the AgenticUQ Workshop at ICML 2026, assigns model tier per trajectory step in under 5ms. In a 7-step document analysis workflow, the research found that only 2 steps required frontier-class reasoning. AgentRouter, ICML 2026 Routing accuracy reached 91% on minimal-complexity steps and 85% on efficient-tier steps. The implication is that subtask complexity varies widely within a single trajectory, which makes step-level routing — not workflow-level routing — the right unit of analysis.
The counterpoint deserves direct treatment. Several recent routing approaches — commercial routers included — fail to consistently outperform a simple heuristic under unified evaluation, according to the AI//COST analysis of 2026 routing benchmarks. LLM routing by task complexity: the 2026 evidence (AI//COST, August 2026) One study testing small language models as front-door routers found that its own viability bar — 0.85 accuracy at 2,000ms P95 — was met by none of the models tested. The best exact-match score was 0.783. AI//COST (2026)
Routing wins when the router itself is reliable, quality constraints are enforced, and the task distribution is stable enough that the router’s training data reflects production reality. None of those conditions is guaranteed by choosing a routing architecture.
The cold-start problem and the cascade fallback
One underappreciated failure mode is cold-start: existing routers generalise poorly when in-domain training data is unavailable. Research from Nanyang Technological University and City University of Hong Kong addresses this with a multi-level task-profile–guided data synthesis framework that constructs a hierarchical task taxonomy to approximate the target distribution. Task-Aware LLM Routing, ACL 2026 This matters practically for any team routing a new task category without historical query logs — which is the situation at the start of most deployments.
Cascading offers a partial answer to cold-start risk. Where a router requires calibrated training data, a cascade requires only a quality check on the output. Route-To-Reason (RTR), published at ACM Web Conference 2026, frames the problem as simultaneous selection of model and reasoning strategy based on query complexity and budget. RTR, WWW ’26
The AI//COST analysis offers a useful decision formula for cascades: let c be the cheap model’s cost for the task, C the flagship’s, and f the fraction of tasks the cheap model fails. If c + f × C < C, the cascade saves money. AI//COST (2026) That condition holds when failure rates stay below roughly 30–40%, depending on the cost gap between tiers. A higher failure rate erodes the saving; at some point the cascade costs more than the flagship alone.
Three operational decisions, not one vendor selection
Routing is not a one-time infrastructure choice. The IoT Digital Twin PLM benchmark is explicit on this: treat the small-versus-large question as an empirical, ongoing measurement. IoT Digital Twin PLM (June 2026) In a mature agentic system, the same session may invoke both model sizes dozens of times, choosing per step.
Instrument before you route. You need per-task quality metrics and a cost baseline before a router can be calibrated. Without them, you are optimising against nothing.
Define your quality floor explicitly. RouteNLP’s framework enforces per-task quality constraints, not just a cost target. That constraint is what keeps routed outputs competitive with frontier quality. A cost-only target will degrade output on tasks where the small model is marginal.
Build the validator. For structured tasks, a deterministic check on the output catches the small model’s occasional miss before it propagates. For generation tasks, a proxy reward model or a human spot-check sample serves the same function. Without a validator, a lower capture rate on the small model directly lowers your effective quality — there is no mechanism to recover it.
Routing does not fit every situation. If your task distribution is genuinely unpredictable, your query volume is low enough that engineering cost exceeds inference savings, or you lack the labelled data to calibrate a router, single-model deployment is the right call for now. The practical test is whether your monthly inference bill reflects the actual complexity distribution of your queries. If it does not, the measurement work to find out by how much is worth doing before any routing infrastructure is built.
Next action: Pull your last 30 days of query logs, classify a sample of 200 requests by complexity tier — simple factual or schema-bound, moderate single-step reasoning, complex multi-step — and calculate what each tier currently costs you. That analysis tells you whether the routing opportunity is large enough to justify the calibration work, before you write a line of router code.
— Eagentix
Eagentix helps growth-focused enterprises redesign and automate manual business processes. We combine executive strategy, implementation support, and managed services to build dependable operations across Southeast Asia.
Sources
- Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey
- Task-Aware LLM Routing with Multi-Level Task-Profile-Guided Data Synthesis for Cold-Start Scenarios
- Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey
- Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey
- RouteNLP: Closed-Loop LLM Routing with Conformal Cascading and Distillation Co-Optimization
- Small LLM vs Large LLM: How to Route by Task Complexity – Tencent Cloud
- Small language models as front-door routers
- Source: Adaptive Model and Strategy Routing for Cost-Efficient LLM Services | Proceedings of the ACM Web Conference 2026 (
- Source: Small vs Large LLMs for Agentic Tasks: A 2026 Benchmark – IoT Digital Twin PLM (
- Source: Task-Aware LLM Routing with Multi-Level Task-Profile-Guided Data Synthesis for Cold-Start Scenarios – ACL Anthology (
- Source: AgentRouter: Heterogeneous Model Routing — AgenticUQ @ ICML 2026 (
- Source: A Systematic Survey of Large Language Model Routing (
- Source: LLM routing by task complexity: the 2026 evidence · AI//COST (