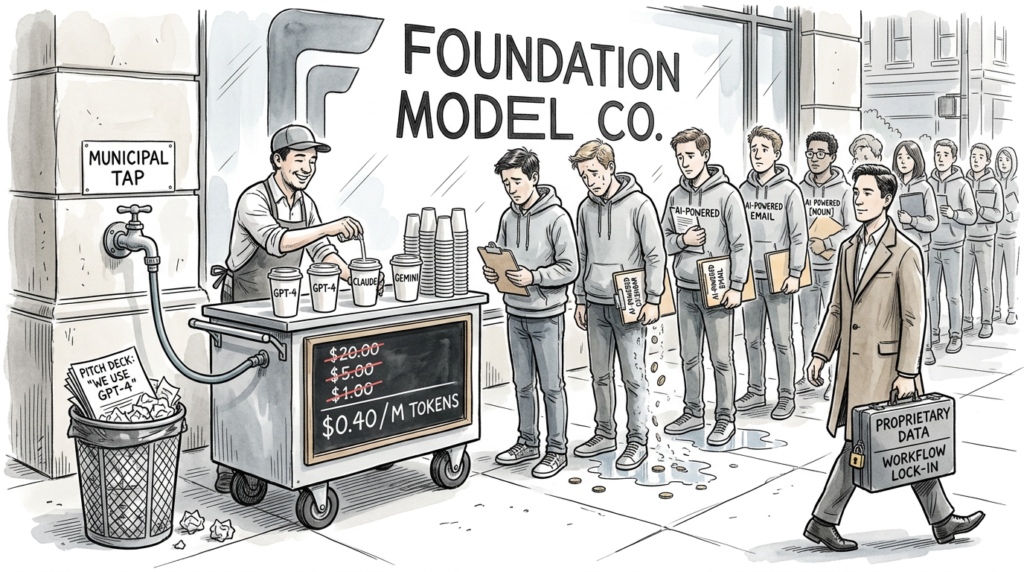
Model access became a line item
Frontier-class inference cost fell from roughly $20–$30 per million input tokens in the early GPT-4 era to approximately $0.40 by early 2026 — a 50x–75x decline, according to The Great Commoditization. Enterprise blended inference costs fell 67% in a single year, from around $18.40 per million tokens in Q1 2025 to $6.07 in Q1 2026. StratoFactory’s central forecast, as reported in that same piece, projects that figure falling further — from $4.75 in 2026 to $1.57 by 2030, a decline of roughly two-thirds over four years.
That trajectory has one practical consequence: model access is a commodity input, comparable to bandwidth or cloud compute. Saying “we use GPT-4” in a pitch deck carries roughly the same strategic weight as saying “we use AWS.” It describes infrastructure. It does not describe a business.
A significant portion of the AI startup ecosystem was built on exactly that premise: wrap a capable model, charge a margin above API cost, grow fast enough to matter. The margin collapsed faster than the growth arrived — and the model providers kept shipping.
What the failure data shows
Approximately 80% of AI wrapper startups are projected to fail by end-2026, with 90-day churn rates near 65% compared with a 35% SaaS average, according to Value Add VC. Over 200 GPT-wrapper startups were cannibalized by OpenAI’s own native feature releases in 2024 alone. Inference cost per million tokens dropped roughly 80% from 2023 to 2025, destroying the margin model for any startup whose unit economics depended on the spread between API cost and customer price.
Value Add VC’s editorial puts it directly: “80% of AI wrapper startups are on track to fail by the end of 2026 because they were never companies to begin with — they were features waiting for their model provider to ship the same capability for free. Churn rates near 65%, a 200+ startup casualty count from OpenAI’s 2024 roadmap alone, and an 80% collapse in inference pricing all point to the same conclusion: the moat has to exist somewhere the foundation model can’t reach, or the startup is just borrowed time on someone else’s product roadmap.”
This is not a capital problem. By close of 2025, the AI sector had absorbed $202.3 billion — nearly 50% of all global startup funding, per Baytech Consulting. Capital was not scarce. Defensibility was.
Differentiation has migrated one layer up
The commoditization of inference does not reduce AI’s value — it concentrates value at the application layer. When the model is cheap and interchangeable, the scarce resource becomes what the model cannot supply on its own: domain-specific workflows, proprietary data that accumulates through use, embedded distribution, and institutional knowledge that takes years to encode.
Baytech Consulting frames it directly: “Simply utilizing a third-party LLM to perform basic task automation is no longer a viable business strategy; it is merely a feature that will inevitably be commoditized by the foundation model providers themselves.”
Consider what OpenAI, Anthropic, and Google can replicate readily: general-purpose chat, document summarisation, code completion, image generation. Then consider what they cannot replicate at scale: a decade of annotated clinical records from a single hospital network, a proprietary dataset of machinery failure signatures, or a workflow so embedded in a customer’s operations that replacing it would cost more than a year of licence fees. The gap between what the model can do and what the application knows is where durable advantage now sits.
The strongest counterpoint, answered fairly
The credible objection is that application-layer moats are also under pressure. Foundation models are improving at 5x–10x algorithmic efficiency per year on reasoning, math, and software engineering tasks, per an arXiv analysis cited in The Great Commoditization. A workflow requiring significant prompt engineering today may require almost none in 2027. Data that is hard to replicate now may become less decisive as models generalise better. That pressure is real, and a slower data flywheel or shallower workflow integration does reduce the durability of any moat built on those foundations.
The counterpoint sharpens the thesis rather than defeating it. The same argument was made about cloud commoditising SaaS in 2012. Cloud did commoditise generic software. What survived was software with deep process integration, strong network effects, and switching costs embedded in customer operations. Application-layer AI companies that will be standing in 2030 are those building those same structural characteristics.
Distribution compounds in ways that model quality does not. A proprietary data flywheel — where each customer interaction makes the product more accurate for the next — is structurally different from a feature any model provider can ship in a quarterly update. The AI agent market, which Foundra notes barely existed in 2024 and is projected to reach $50 billion by 2028, is the clearest current signal of where that flywheel logic is being applied.
The diagnostic and the decision
If you are building or funding an AI product, the operative question is not “which model are we using?” It is “what does our product know or do that the model provider cannot replicate by shipping a native feature?” If the honest answer is “not much yet,” that is a roadmap problem — one that needs resolving before the next model release cycle, not after.
Three places where application-layer moats tend to be most durable:
- Proprietary data generated through use. Data your product creates through customer interaction compounds over time. Data you purchase or scrape does not accumulate the same way and is more easily replicated.
- Workflow depth with genuine switching costs. Integration that sits inside a customer’s existing processes — not alongside them — creates replacement costs that general-purpose AI cannot easily undercut.
- Distribution in channels the model providers do not own. Regulated industries, professional communities, and deeply embedded enterprise integrations create structural barriers that are harder to replicate than any model capability.
API orchestration alone does not qualify. Neither does a clean UI on top of a commodity model. The test is whether your product becomes harder to replace as a customer uses it more — and whether what makes it harder to replace is something you own, not something you license.
Inference will keep getting cheaper. StratoFactory’s $1.57-per-million-token forecast for 2030 may prove conservative rather than aggressive. That is good news for operators who have built at the right layer. For those still treating model access as the product, the window to reposition narrows with every quarterly price cut.
— Abhijit Ghosh
If this framing is useful, join the conversation below or subscribe for weekly breakdowns on where AI competitive advantage is actually being built.
Eagentix helps growth-focused enterprises redesign and automate manual business processes. We combine executive strategy, implementation support, and managed services to build dependable operations across Southeast Asia.
Eagentix helps growth-focused enterprises redesign and automate manual business processes. We combine executive strategy, implementation support, and managed services to build dependable operations across Southeast Asia.
Sources
- – How to Start an AI Startup: Practical Guide (2026) | Foundra
- – The Commoditization of the AI Infrastructure Layer | Alok Agrawal
- – The Great Commoditization: When the Model Stopped Being the Moat
- – Why Generic AI Startups Are Dead: Playbook for Moats
- – Why Most AI Startups Are Building Features, Not Companies
- – AI Token Futures Market: Commoditization of Compute and Derivatives Contract Design
- – AI Startup: definition, the three categories (foundation, infrastructure, application), and what makes one defensible | Startups.com
- – The Model Is Free. The Inference Is the Business.
- – 2025 Startup Shutdowns: AI Companies with No Data Moat | Itamar Novick posted on the topic | LinkedIn
- – The Harness as the Agentic Moat – by Gennaro Cuofano
- – Beyond Functionality: Building Durable ‘Moats’ in the AI Era
- – Competitive Moats in the AI Era | Future of Competitive Advantage in AI | Exeed College
- – Competition in the AI Era: What Will Make or Break Businesses in the Age of AI Agents · Digital Bank Expert
- – AI execution commoditization: finding your $40 competitiv… | Ability AI
- – Sustainable AI Advantage: What Still Compounds | Viren Lall
- – AI-Era Competitive Advantage: Learning Speeds Up
- – Only the Paranoid Build Moats: Rethinking Durable Advantage in the AI Era | by Adnan Masood, PhD. | Medium
- – Market Commoditization of Products and Services
- – Understanding ‘Trendslop’ via HBR Research
- – Marketing strategy and firm value under commoditization
- – The March 2026 AI Model War: Why Intelligence Just Became a Utility | by Kumar Ankit | Medium
- – TOP Venture
- – Market Insight: AI Bubble Risk And Capital Cycles
- – Insights & Research | Wing Venture Capital
- – The AI Profit Map: Why the Biggest Winners Aren’t Who You Think
- – The 7 Layers of Agentic AI Stack
- – OpenClaw (aka Clawdbot) and the AI Threshold Effect
- – The Coming Software Commoditization: How fintech must …
- – Inside Talus: The Infrastructure for Onchain Autonomous Agents
- – From SaaS to AGaaS – by Gennaro Cuofano